PromptMule
Cloud caching service for GenAI promptsFaster, traceable prompt caching
Highlights
What you can do with it
- Caching prompts so AI applications respond faster
- Monitoring and tracing AI decisions in production
- Reducing repeated calls for the same or similar prompts
How to use it
- 1 Sign up for the free basic plan or a premium plan
- 2 Connect your application to the PromptMule cache
- 3 Route your prompts through the caching layer
- 4 Review the analytics to understand usage and behavior
Who it is for
Pros
- Free basic plan to start with
- Analytics and traceability help with transparency
- AWS-based infrastructure for speed and uptime
Limitations
- The site was not responding at review time, so availability is uncertain
- Premium features, storage, and capacity cost money
- Adds another dependency to your application stack
What PromptMule is
PromptMule is a caching service designed for generative AI applications. It stores frequently used or recently accessed prompts in the cloud so that an application can retrieve them faster than it would from a traditional database. Beyond speed, the service focuses on trust, traceability, and transparency: it provides detailed analytics so developers can see and monitor the behavior and decisions of the AI they operate. The infrastructure runs on AWS, and pricing ranges from a free basic plan to premium plans that add features, storage, and capacity.
What you can do with it
- Cache prompts in the cloud for faster retrieval
- Track usage and behavior with detailed analytics
- Trace AI decisions to support transparency requirements
- Scale from a free plan to premium capacity as your app grows
Who it is for
- Developers building and operating generative AI applications
- Teams that need traceability for the AI decisions they ship
- Operations staff watching response times and infrastructure efficiency
What to watch out for
At the time of review the site was not responding, so you should confirm the service is available before planning around it. The free basic plan has limits, and the premium plans that add storage and capacity cost money, so model your usage before committing. Adding a caching layer is another dependency in your stack, which means another thing to monitor and another point of failure, so weigh the speed gains against that operational cost. As with any AI tooling, the analytics help you understand what happened, but they do not by themselves make the AI correct. Processing speed depends on file size and network conditions, so retry later if a task stalls during peak hours.
FAQ
What is PromptMule?
It is an AI caching service that stores prompts in the cloud and provides analytics and traceability for GenAI applications.
Is there a free plan?
Yes, pricing ranges from a free basic plan to premium plans with more features, storage, and capacity.
What technology does it use?
It uses AWS cloud infrastructure to deliver performance, uptime, and efficiency.
Why it is free
What the official page says: 免费
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
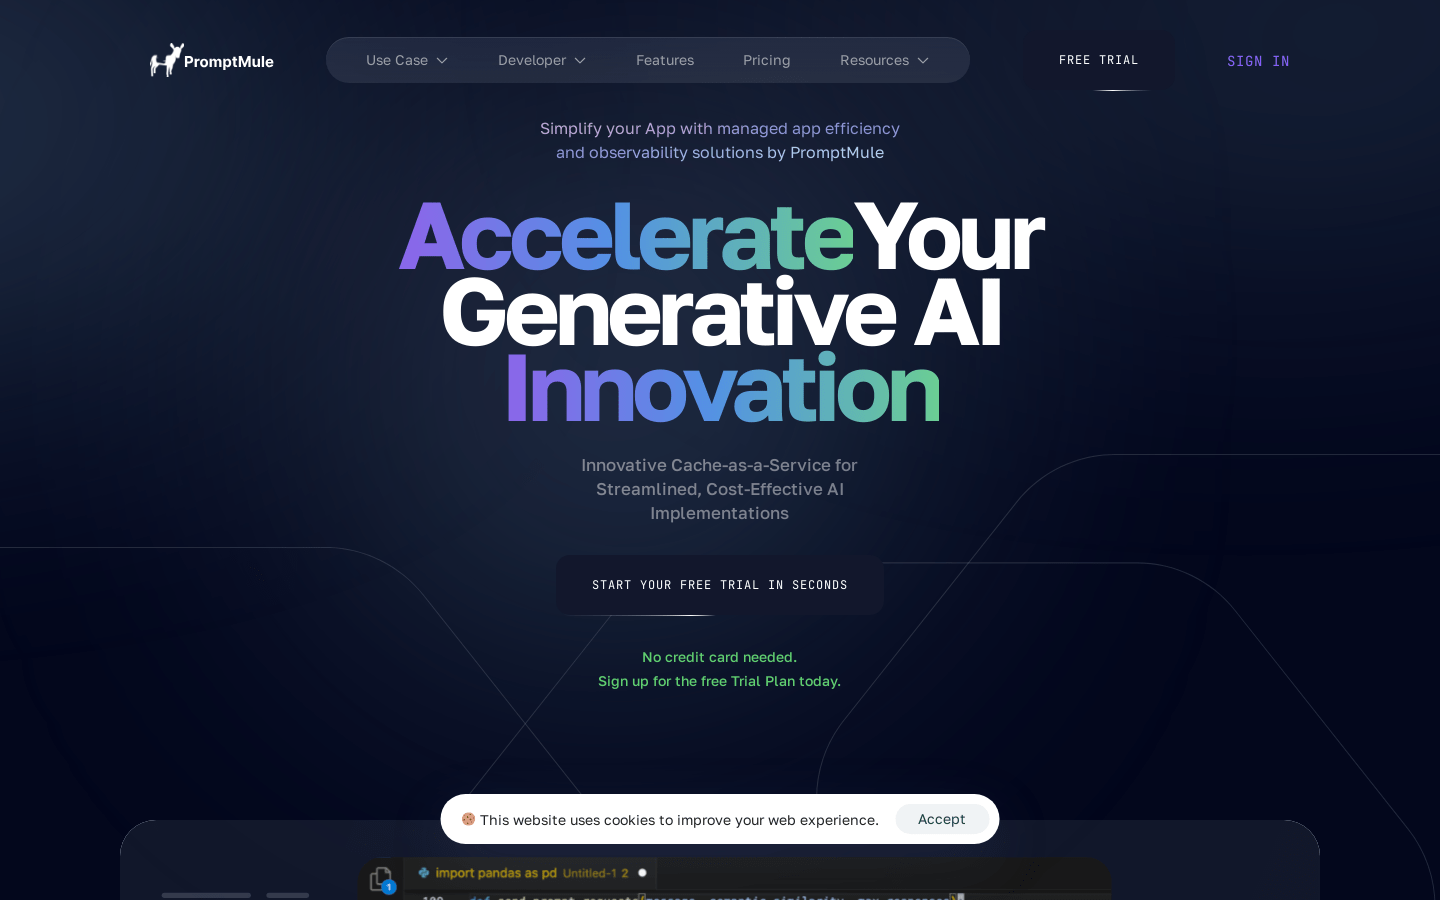
Screenshot archived from the listing page, for preview only.