Chunkr
Open-source document ingestion API for RAG pipelinesTurn documents into structured, model-ready data
Highlights
What you can do with it
- A business converts PDF tickets into structured records for analysis
- A researcher turns academic papers into machine-readable text
- A school converts textbooks and notes into digital course content
How to use it
- 1 Register for an account on the Chunkr website.
- 2 Create a new ingestion task after logging in.
- 3 Upload a PDF, DOC, PPT, or XLS file.
- 4 Let the service run layout analysis, OCR, and chunking.
- 5 Download the structured data or pull it through the API.
- 6 Move the output into your analysis, training, or business pipeline.
Who it is for
Pros
- Handles layout, OCR, and chunking in one service
- Free credits of 1500 pages cover early testing
- API first, so it drops into an existing pipeline
- Open source, with documentation and GitHub resources
Limitations
- Credits run out, and larger volumes need a paid plan
- Scanned and handwritten input is less reliable than clean text
- Complex layouts still need manual checking
- You own the accuracy of anything downstream of the output
What Chunkr is
Chunkr is an open-source data ingestion API service. Its job is to take a document and turn it into structured data that a machine can use: layout analysis to find where blocks of content sit, OCR to read text from scans and images, and chunk processing to split the file into text, tables, images, and handwritten sections. The output is shaped for retrieval augmented generation and other LLM applications. It handles PDF, DOC, PPT, and XLS files, exposes an API with documentation, and is maintained by Lumina AI Inc. New accounts get 1500 pages of free usage credits, with paid plans for larger volumes.
What you can do with it
- Run layout analysis on a mixed-format document
- OCR scanned pages and images into machine-readable text
- Split content into structured chunks, tables, and image references
- Pull the result through an API into your own pipeline
- Feed clean structured data into RAG or model training
Who it is for
- Developers building RAG or LLM features over document collections
- Teams digitizing paper records, tickets, and scanned archives
- Researchers preparing text corpora for analysis or mining
What to watch out for
Structured output is only as good as the input. Clean digital PDFs process well, while low-quality scans, handwriting, and unusual layouts degrade fast and need manual checking. Table detection in particular is worth verifying before you rely on it downstream. The 1500 free pages are a starting allowance, not a permanent free tier, and larger volumes need a paid plan. Anything you build on top of the output inherits its errors, so spot-check a sample before you scale a pipeline on it.
FAQ
Is Chunkr open source?
Yes. The listing describes it as an open-source data ingestion API service maintained by Lumina AI Inc.
What file types are supported?
PDF, DOC, PPT, and XLS files are listed, including scanned documents handled through OCR.
How much can I process for free?
The listing mentions 1500 pages of free usage credits to help users get started. Larger volumes need a paid plan.
Why it is free
What the official page says: free trial
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
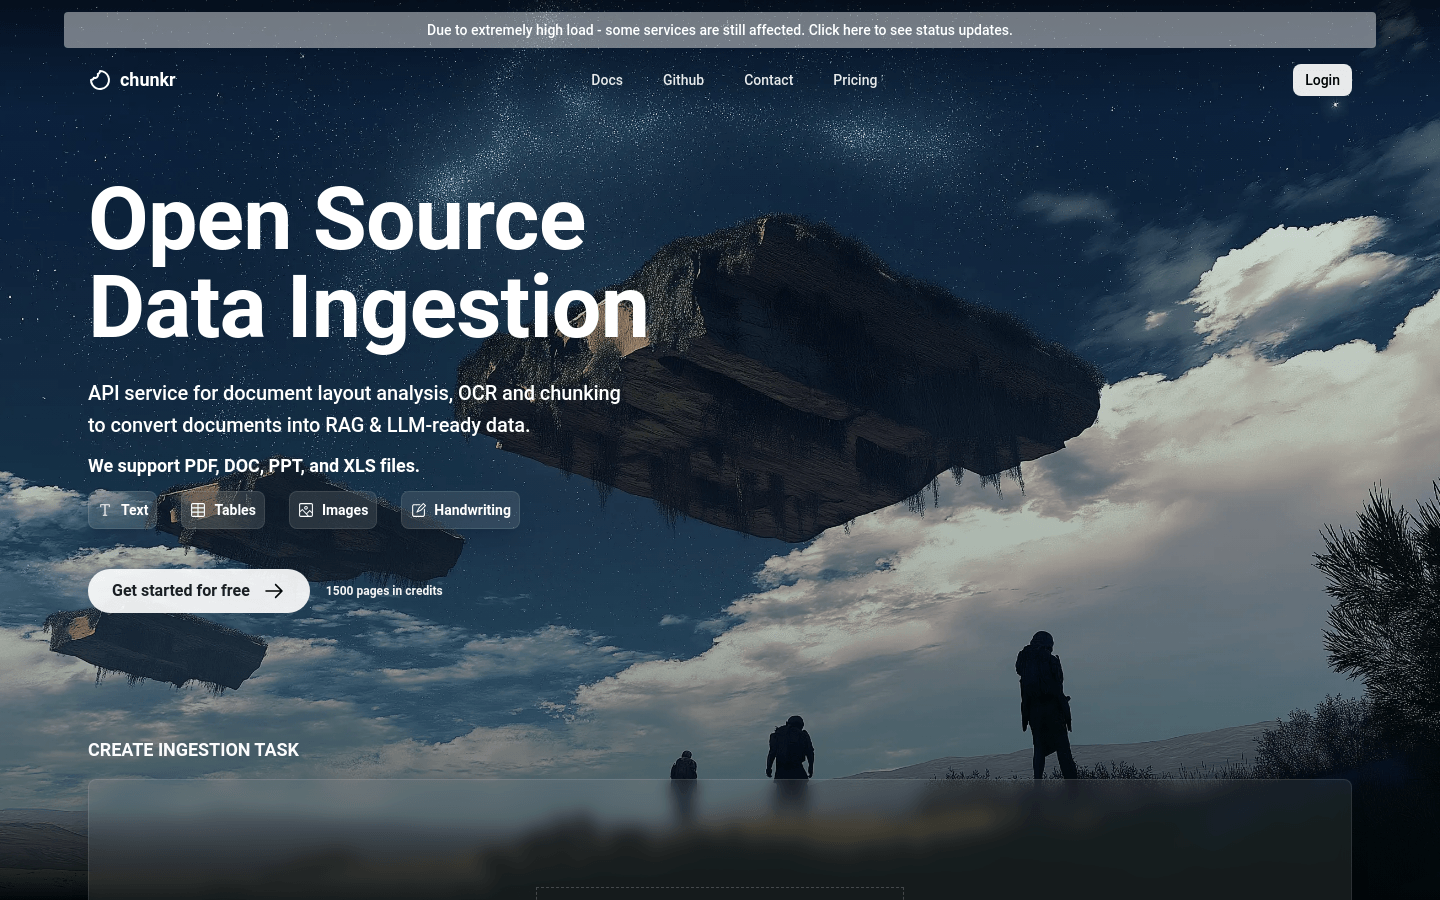
Screenshot archived from the listing page, for preview only.