MediaTek Research Breeze-7B
Open-source 7B bilingual language modelChinese and English handling from MediaTek Research
Highlights
What you can do with it
- Run bilingual real-time translation
- Power a Chinese and English customer service bot
- Analyze or generate tabular content in two languages
How to use it
- 1 Download the open-source MR Breeze-7B model.
- 2 Set up an environment able to run a 7B parameter model.
- 3 Load the model and test it on your bilingual tasks.
- 4 Fine-tune or prompt it for translation, service, or analysis work.
Who it is for
Pros
- Open source and free to use
- Handles traditional Chinese nuance better than its predecessor
- Optimized for response speed
Limitations
- 7B parameters need real hardware to run locally
- Smaller models lag larger ones on hard reasoning
- Release and support depend on the upstream lab
What MediaTek Research Breeze-7B is
MediaTek Research has released MR Breeze-7B, an open-source large language model with 7 billion parameters that specializes in Chinese and English. Compared with the earlier BLOOM-3B, it absorbed roughly 20 times more knowledge, which is why it handles the cultural and linguistic nuances of traditional Chinese more accurately. It is optimized for speed, and the listing says it is free to use. Common applications are bilingual translation, intelligent customer service, and data analysis, including parsing and generating tabular content.
Being open source is the practical point for many teams, because it means the weights can be inspected, hosted internally, and fine-tuned without a vendor agreement. A 7 billion parameter model is small by current standards, which is what makes it runnable on modest hardware, and the traditional Chinese focus gives it a specific niche that general models often handle less well.
What you can do with it
- Run Chinese and English generation or translation
- Handle traditional Chinese text with better nuance
- Power a bilingual customer service assistant
- Parse and produce tabular content
- Host the model yourself for data control
Who it is for
- Developers building bilingual applications
- Researchers studying Chinese and English model behavior
- Teams that want a self-hosted model for data control
- Product teams serving traditional Chinese users
What to watch out for
A 7 billion parameter model needs serious hardware to run locally, so plan for a capable GPU or a hosted setup, and the speed advantage does not remove the hardware requirement. Models of this size still trail much larger ones on complex reasoning, long context, and factual accuracy, so verify important outputs rather than trusting them. The release, weights, and any support come from MediaTek Research, and availability can change. Check the license terms before using the model in a commercial product, and benchmark it on your own data before committing.
FAQ
How large is the model?
7 billion parameters.
Which languages does it handle?
Chinese and English, including traditional Chinese nuance.
Is it free?
Yes, it is an open-source model and free to use.
Why it is free
What the official page says: free to use
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
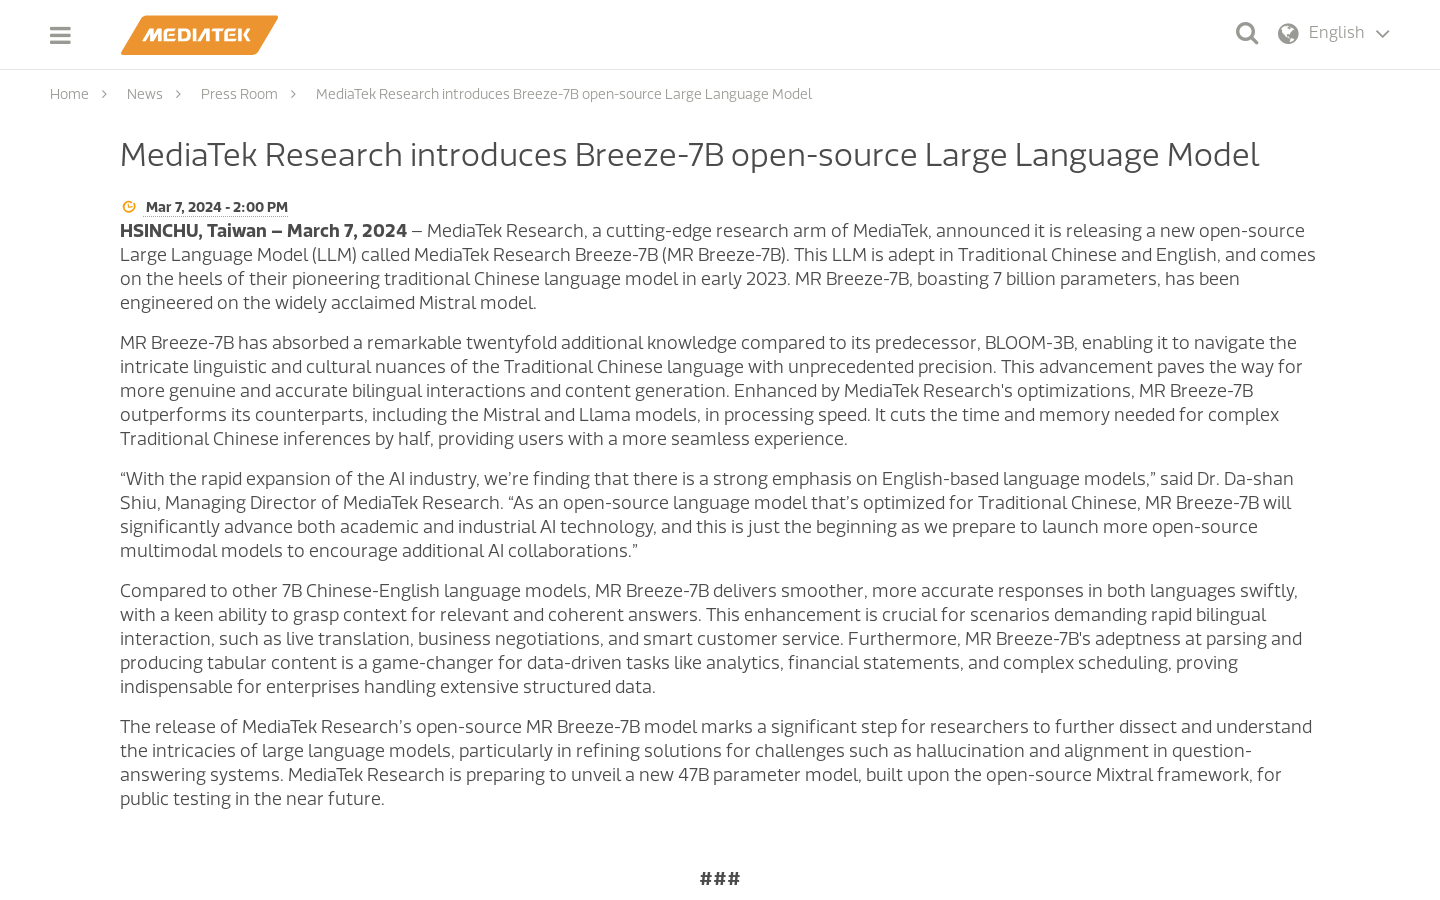
Screenshot archived from the listing page, for preview only.