Whisper Speech
Open-source text-to-speech systemFree, multilingual, developer-friendly TTS
Highlights
What you can do with it
- Build multilingual text-to-speech applications
- Run speech synthesis experiments
- Develop personalized voice applications
How to use it
- 1 Get the open-source Whisper Speech model
- 2 Choose an input format such as Python or Docker
- 3 Set up the deployment environment
- 4 Feed text in your chosen language
- 5 Generate and integrate the speech output
Who it is for
Pros
- Open source and completely free
- Broad language and format support
- Flexible deployment choices
- Built for developers and researchers
Limitations
- Free and open-source terms may change
- Needs technical setup to deploy
- Quality varies by language and input
What Whisper Speech is
Whisper Speech is a fully open-source text-to-speech model. It was trained by Collabora and Lion on the Juwels supercomputer, and it supports multiple languages as well as a range of input formats, including Node.js, Python, Elixir, HTTP, Cog, and Docker. The model's strengths are efficient speech synthesis and flexible deployment options, which let you run it in the way that fits your project. Whisper Speech is completely free and is aimed at developers and researchers who want a powerful and customizable text-to-speech solution they can control.
What you can do with it
- Synthesize speech in multiple languages
- Choose from many input formats such as Python or Docker
- Deploy the model in a way that fits your stack
- Build multilingual text-to-speech applications
- Run experiments with a customizable open model
Who it is for
- Developers adding text-to-speech to applications
- Researchers running speech synthesis experiments
- Student teams prototyping personalized voice apps
- Teams that want to host their own TTS service
What to watch out for
Whisper Speech is open source and free, but the license and distribution terms can change as the project updates, so confirm the current terms before you build on it. Setting it up needs technical skill, and you have to manage your own deployment, which may involve real compute and maintenance costs. Speech quality can vary by language and by the text you feed in, so test with your own data. Treat it as a developer and research tool rather than a one-click consumer app, and check that your hardware and environment can run the model. For best results, start with a small test file and review the output carefully before working on anything important.
FAQ
Is Whisper Speech free?
Yes, it is completely free and open source.
Who trained it?
It was trained by Collabora and Lion on the Juwels supercomputer.
Which input formats are supported?
Node.js, Python, Elixir, HTTP, Cog, and Docker, among others.
Who is it for?
Developers and researchers who need a customizable TTS solution.
Why it is free
What the official page says: completely free
Free limits, trial length and features are decided by the official site and can change at any time.
Product preview
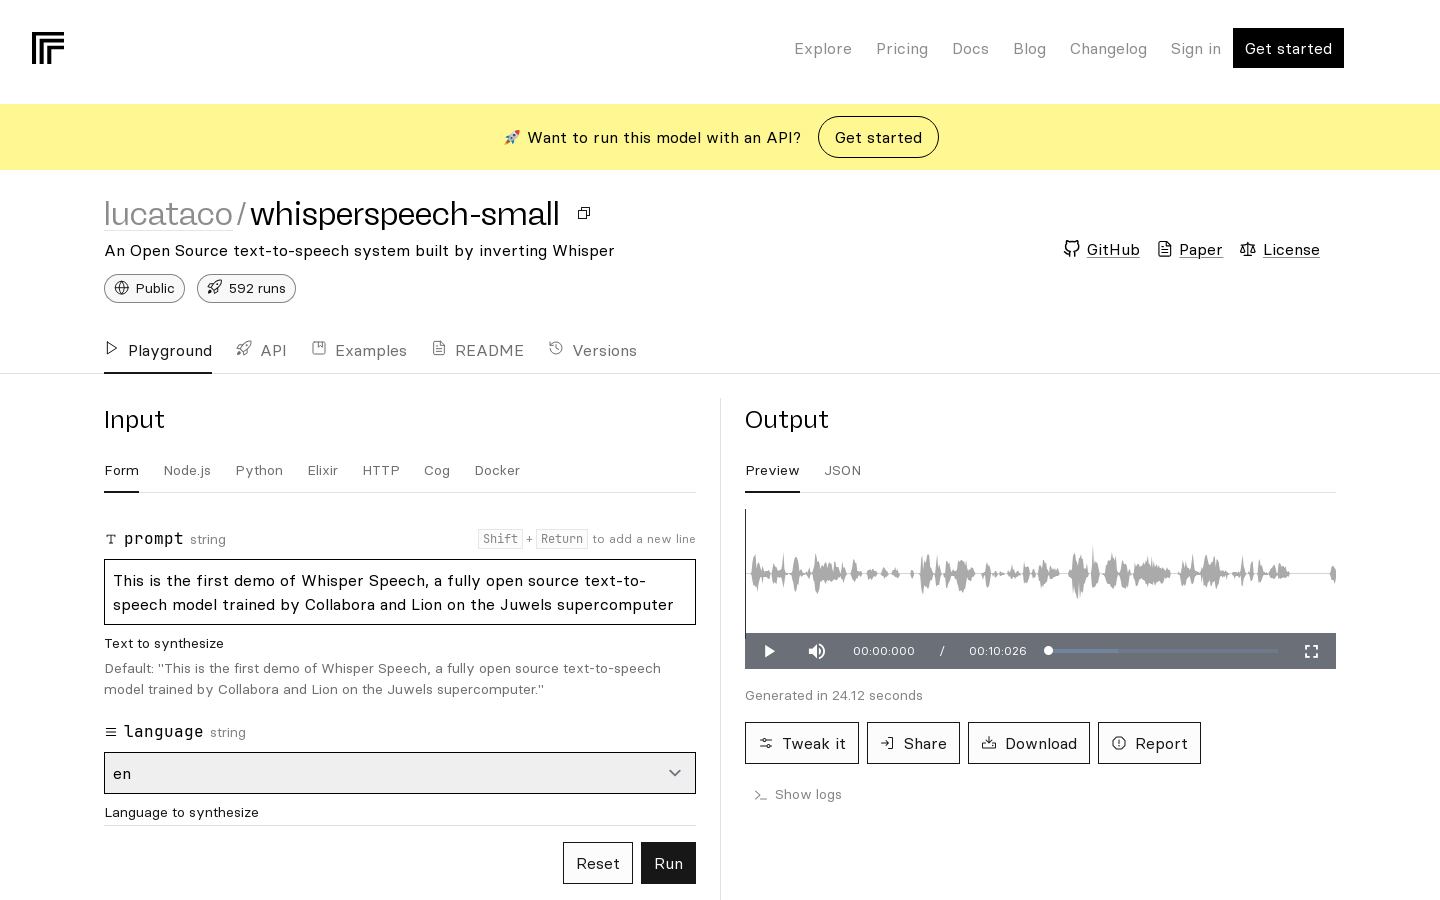
Screenshot archived from the listing page, for preview only.